Multimodal AI Today: How Enterprises Use Documents, Voice, and Vision
Businesses collect information in dozens of formats every day. Customer conversations are recorded, invoices arrive as PDFs, warehouse cameras capture footage, and employees exchange documents filled with charts, images, and handwritten notes. Making sense of all that information often requires moving between systems that weren’t designed to work together.
Multimodal artificial intelligence (AI) is changing how companies handle these workflows by processing different types of information within connected systems.
Today, multimodal AI is already being used in enterprise operations, helping organizations extract information from documents, analyze speech, interpret images, and automate tasks that previously required considerable manual effort.
Multimodal AI – An Overview
Multimodal AI refers to artificial intelligence models and systems that process multiple types of data, including text, audio, and video.
Traditional AI applications often focus on a single data type. For example, a speech recognition system converts audio into text, while computer vision models analyze images.
Multimodal systems can combine information from several sources, allowing organizations to understand the relationships between them.
Consider an insurance claim containing a written description, photographs of vehicle damage, and a recorded customer statement. A multimodal AI pipeline can extract information from each source and bring the results together to support the claims review process.
How enterprises are using multimodal AI today
Modern multimodal AI applications are increasingly integrated into existing business workflows and are no longer a future idea. Three areas demonstrate how these systems are being used:
Document processing and data extraction
Enterprises receive enormous volumes of unstructured information through contracts, receipts, invoices, emails, and scanned documents. Multimodal AI combines document understanding, optical character recognition (OCR), and language models to extract information from documents containing text, tables, and images.
For example, Microsoft’s document processing architecture demonstrates how AI can extract information from invoices and contracts, organize it into structured formats, and flag results for human review. These capabilities help businesses reduce manual data entry and make previously difficult-to-access information available to operational systems.
Voice AI and customer interactions
Voice AI allows organizations to process spoken conversations and incorporate the information into enterprise workflows. Customer service teams can use speech recognition and language models to transcribe calls, summarize conversations, and identify issues requiring follow-up.
Voice-enabled AI assistants can also retrieve information from business systems to help employees or customers complete routine tasks. In August 2026, Microsoft reported that Plaud, an AI-powered recording technology company, had expanded its Azure infrastructure to support transcription, summarization, and related AI workloads for more than 2 million users.
For enterprises, integrating voice data with documents and customer records can reduce repetitive administrative work while giving teams better context for each interaction.
Computer vision and visual data
Computer vision enables AI systems to interpret information from images and video.
Manufacturers can use visual analysis to identify potential product defects, while trailers can extract information from product labels and packaging. Logistics companies can also analyze visual records alongside inventory and shipping data.
Combining visual information with text-based records makes these applications more useful. For example, an AI pipeline can examine a product image, extract information from its label, and compare those details with information stored in a product database.
How multimodal AI pipelines work
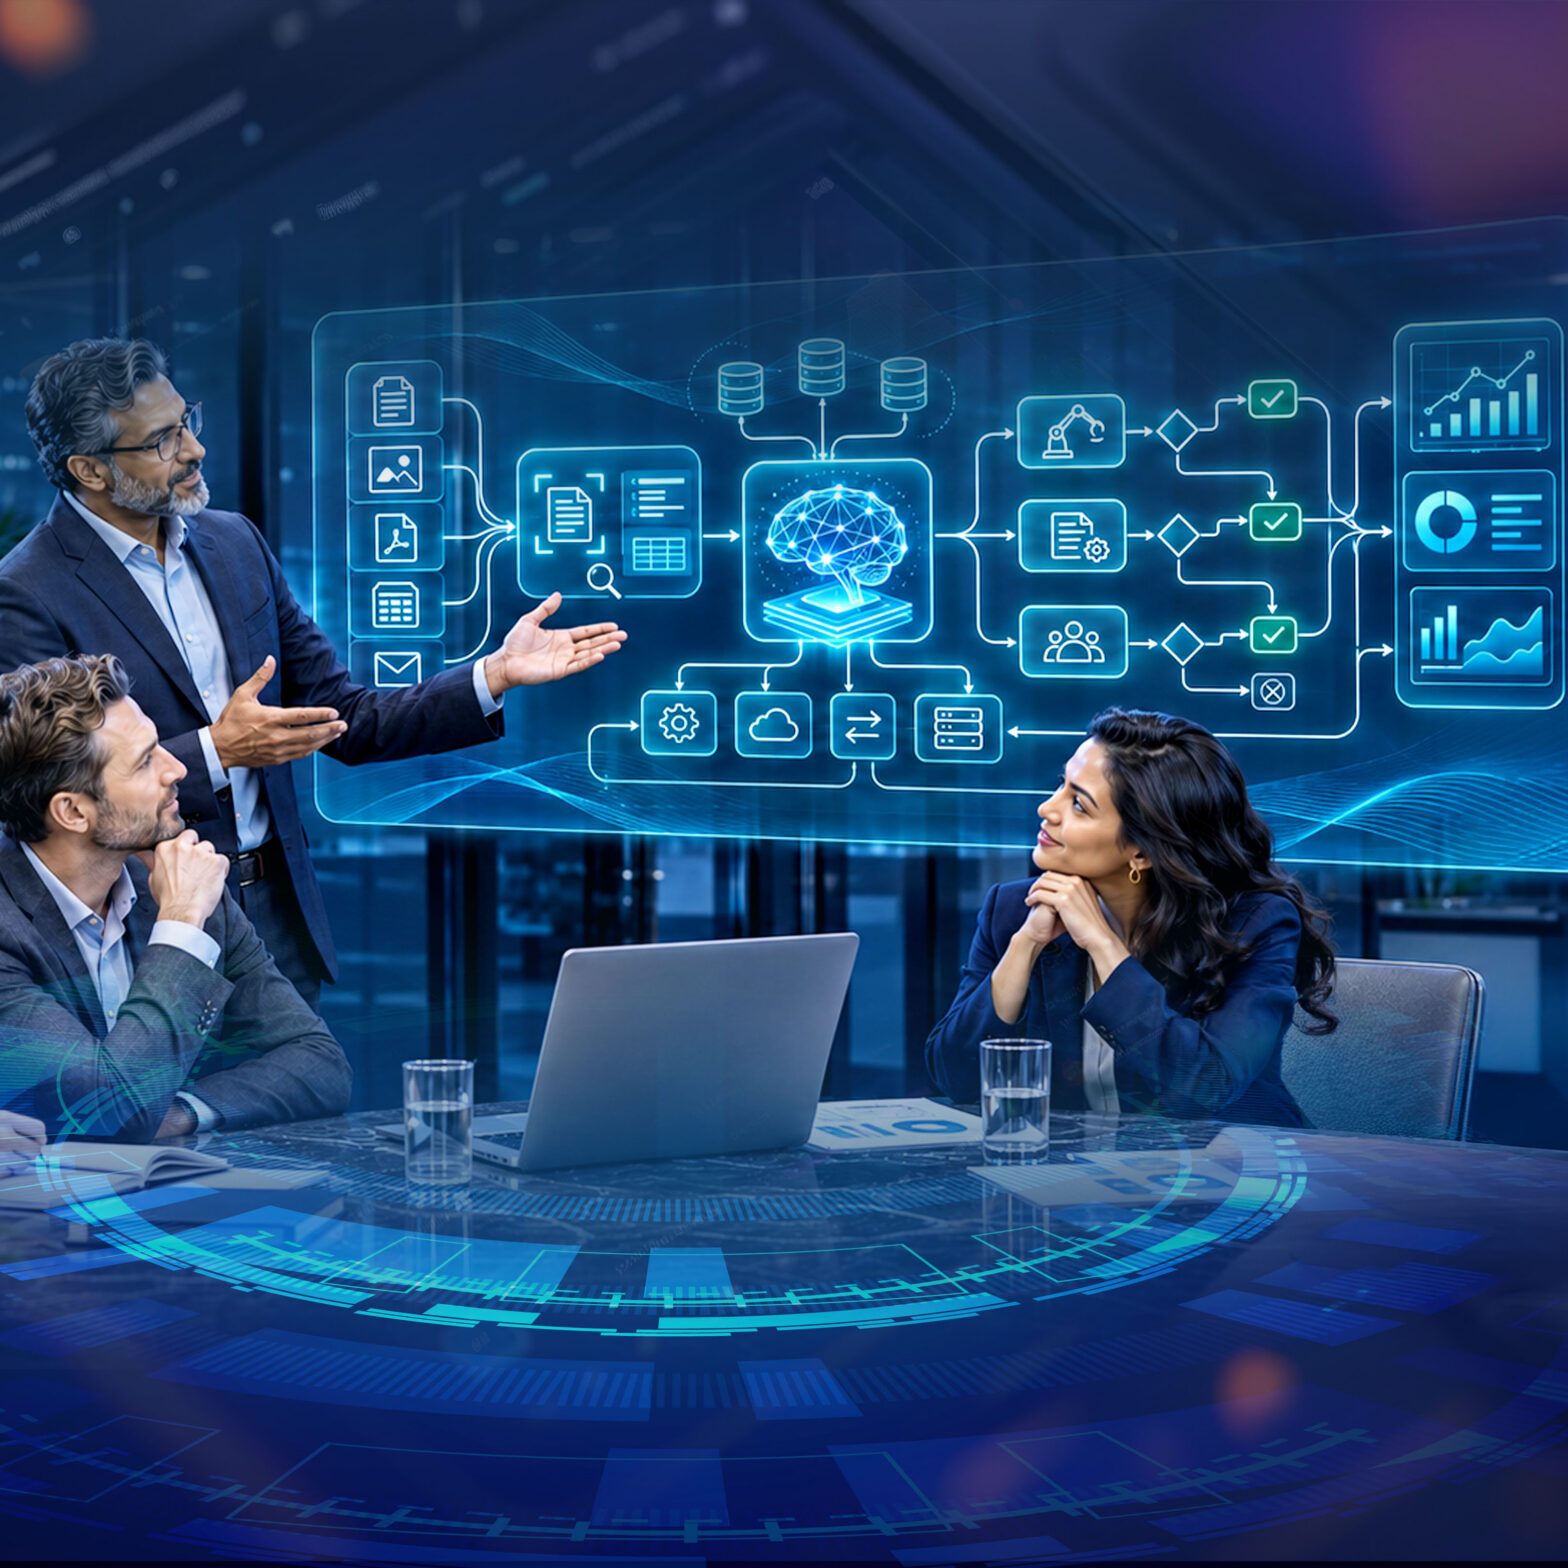
An enterprise multimodal AI pipeline connects different processing technologies into a coordinated workflow. Although implementations vary, a typical pipeline includes:
- Data ingestion: Collecting documents, images, audio recordings, and other information from business systems.
- Processing and extraction: Using AI models to identify relevant content and convert it into usable data.
- Data integration: Combining extracted information with existing records, databases, or enterprise applications.
- Validation and automation: Checking results, routing exceptions for human review, and transferring approved information into downstream workflows.
Some pipelines also use retrieval-augmented generation (RAG), allowing AI applications to retrieve relevant information from enterprise documents, tables, and images when generating responses. These systems require careful attention to accuracy, security, processing costs, and data governance, particularly when handling confidential information.
How Blackstraw applies multimodal AI in enterprise operations
Blackstraw develops multimodal AI solutions that help enterprises process information across documents, images, audio, and video. By connecting AI models with existing business systems, companies can automate data-intensive workflows and make information more accessible across departments.
For a global consumer goods company, Blackstraw developed an enterprise Generative AI platform capable of processing multiple data formats and integrating information from SharePoint, Azure Data Stores, and other enterprise sources.
Other applications demonstrate how these capabilities work in different industries:
- Aerospace manufacturing: Blackstraw developed an Intelligent Knowledge Source Accelerator that extracts text, tables, and images from technical documents, allowing engineers to retrieve relevant information through AI assistants.
- Consumer packaged goods: Blackstraw’s product claims intelligence solution uses computer vision and natural language processing to identify and classify product claims. The system achieved 92-95% accuracy while reducing manual review work by 35-45%.
These implementations demonstrate how multimodal AI can streamline operations that depend on information spread across different formats and systems. By integrating these capabilities into enterprise infrastructure, Blackstraw helps businesses scale automation while maintaining control over their data and AI workflows.
FAQs – Future of Multimodal Models
1. What is multimodal AI?
Multimodal AI refers to models that process and combine information from multiple data modalities, such as text, images, video, and speech, in a single system. Unlike earlier unidirectional models built for one task like speech-to-text or text-to-image, multimodal AI assimilates contextual cues across modalities to deliver a more comprehensive and nuanced understanding of data.
2. How does multimodal AI work?
Multimodal AI works by processing multiple data modalities together rather than in isolation, drawing on contextual cues and supplementary information across each input type to build a nuanced, comprehensive understanding. This differs from earlier multimodal systems, which operated unidirectionally for a single task, such as converting speech to text or text to image.
3. What are the benefits of using multimodal AI for business?
Multimodal AI benefits businesses by combining text, image, and other data types to improve decision-making and automate complex processes. In practice, this has helped optimize job matching for staffing firms by 5 times, parse 1.5 million email orders daily across 64 fields, extract product information from labels with over 90% accuracy, and automate 95% of manual data entry from receipts.
4. What is the difference between single-modal AI and multimodal AI?
Single-modal (unimodal) AI systems focus on one type of data, such as text or images, typically for a specific task like speech-to-text conversion. Multimodal processes multiple modalities such as text, images, video, and speech together, assimilating contextual cues across all of them to produce a more comprehensive understanding than unimodal systems can achieve alone.
5. What are the applications of multimodal AI?
Multimodal AI applications span enterprise use cases that combine text, speech, images, and gestures to mirror human perception and communication. Examples include extracting data from unstructured documents like receipts, invoices, and handwritten timecards, retrieving insights from tables and images through retrieval augmented generation, and combining structured and unstructured data in a single inference cycle through agent orchestration.
6. What are the key trends in multimodal AI in 2026?
Key trends in multimodal AI for 2026 include:
- Agentic systems that pair multimodal understanding with autonomous action
- Domain-specific models built for healthcare, finance, and legal use cases
- Compact, on-premise models chosen for data sovereignty and lower cost
- Faster, near real-time voice and video interactions
- New compliance requirements as the EU AI Act’s high-risk rules take effect in August 2026.
7. What are examples of multimodal AI in business?
Common applications include extracting information from invoices and contracts, analyzing customer calls, interpreting product images, and processing visual inspection data alongside written records.
8. What should enterprises consider before implementing multimodal AI?
Organizations should evaluate data quality, security, system integration, model accuracy, processing costs, and human oversight before deploying multimodal AI pipelines.
Enjoying this article? Share it with the World